
On the structural transformation underneath the metaverse vocabulary, why being comfortable with technology is not the same as understanding it, the five dimensions of the digital literacy that the next generation actually needs, who controls the virtual environments they will inhabit, and what it means when an entire generation grows up believing that the digital world is not separate from reality
The children entering schools today will inherit a world in which artificial intelligence can generate content indistinguishable from human-produced work, virtual environments can simulate physical experiences with increasing fidelity, and digital identities can travel across platforms with the portability of a passport. For them, the internet will not necessarily be something they go onto. It will be part of the environment around them — ambient, spatial, increasingly intelligent, and governed by systems that most of the adults currently building those systems do not themselves fully understand. This is the transformation underneath the terminology. The word metaverse may change. The underlying structural shift will not.
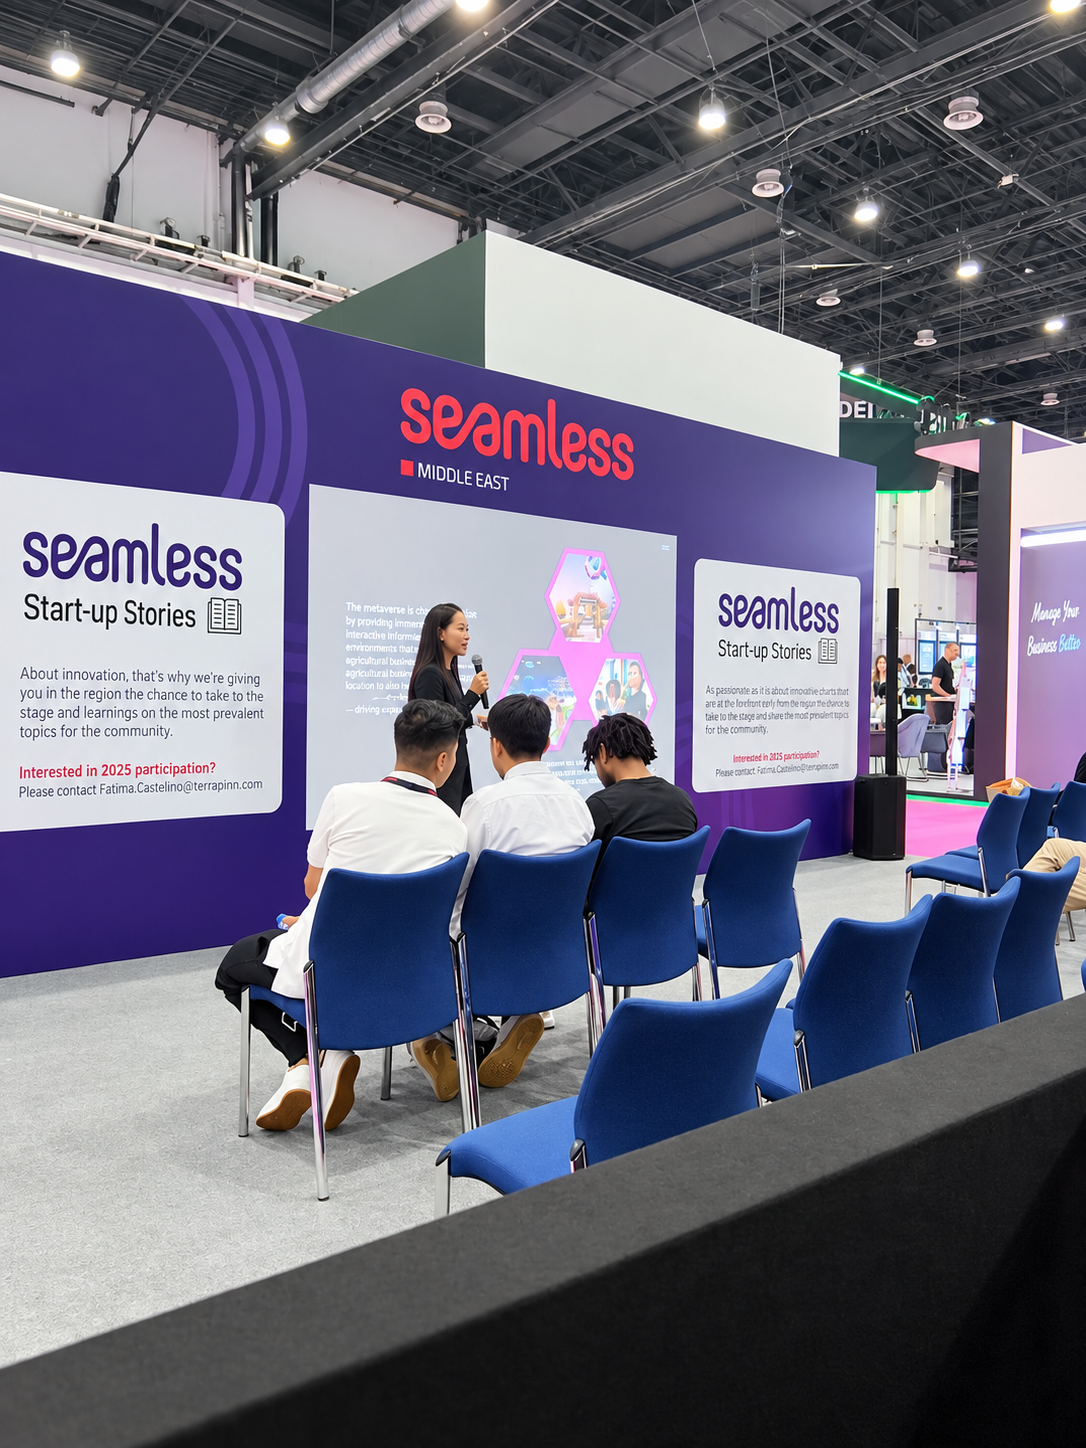
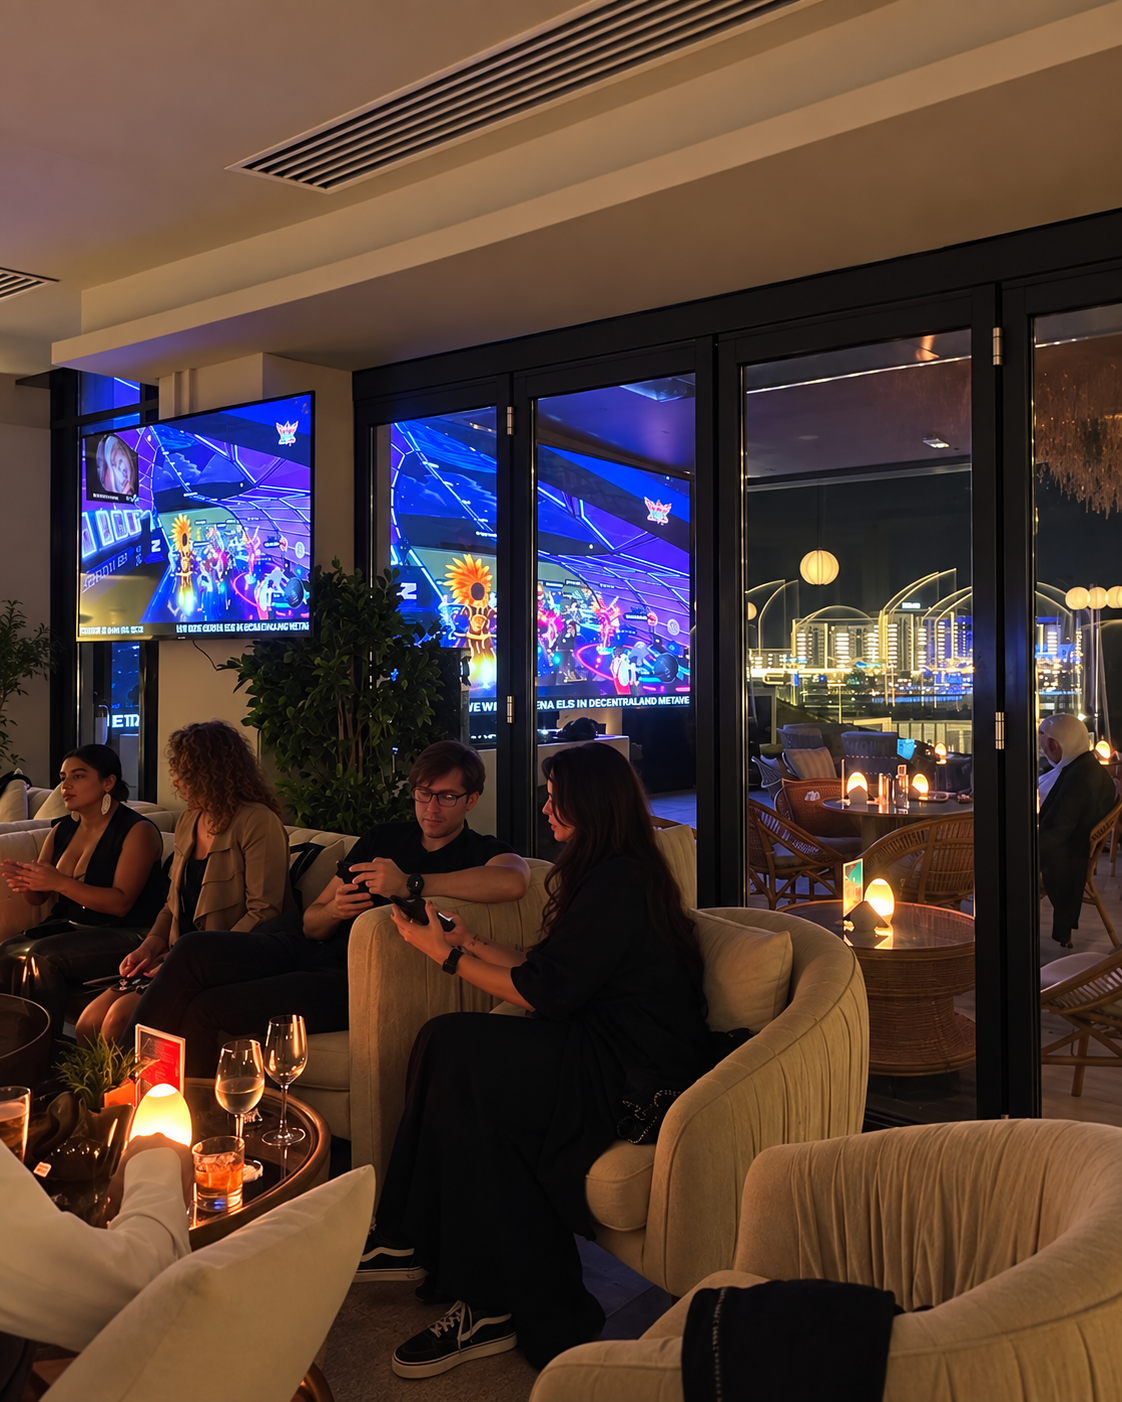
Speaking at Seamless Middle East 2024 — the region’s primary summit for digital commerce and technology — raised a question that no panel discussion fully resolved: what should we be teaching the generation that will inherit the next internet? Not as a technology curriculum question, but as a civilisational one. The answer, this editorial argues, is not primarily technical. It is structural: the next generation needs to understand not only how to use digital environments but how those environments are built, governed, monetised, and experienced. That distinction — between using technology and understanding it — is the most consequential educational challenge of the coming decades.
The internet after the screen — from browsing to presence
The history of digital interaction can be understood as a sequence of expanding spatial metaphors. The early internet was a library — a set of documents that could be retrieved and read. Social media transformed it into a town square: a place of broadcast, response, and social performance. Mobile computing made it ambient, carrying the digital environment into every physical context. The next phase — variously called spatial computing, immersive computing, or the metaverse — proposes the most radical metaphor yet: the digital environment not as a destination to be visited but as a layer superimposed on, or replacing, the physical environment itself.
This is not science fiction. It is already partially operational. Augmented reality — digital information overlaid on physical reality through a screen or eventually through transparent optics — is present in navigation, retail, medical imaging, and manufacturing. Virtual reality — fully immersive digital environments accessed through headsets — is deployed in pilot training, surgical simulation, architectural visualisation, and therapeutic settings. As Deloitte’s analysis of spatial computing documents, the convergence of these technologies with artificial intelligence and high-bandwidth connectivity is creating the conditions for computing that is contextual, spatial, and increasingly invisible as a distinct technology rather than a continuous layer of the environment.
The important point is not that every person will live in virtual reality. It is that computing is becoming less confined to a screen and more embedded in the physical and social environments through which people move. This changes what digital literacy means, what digital education requires, and what digital governance needs to address. The relationship between tool and user has always shaped what kinds of thinking are possible — and the shift from screen to spatial computing is among the most consequential changes to that relationship in computing history. The screen was, in retrospect, a useful containment: it was legible, bounded, and relatively easy to regulate. The spatial internet is none of these things.
What is Spatial Computing — and why does it matter more than the metaverse as a concept?Spatial computing refers to the category of technologies that extend digital interfaces beyond the flat screen into three-dimensional physical and virtual space. It encompasses augmented reality (AR), which overlays digital information onto the physical world; virtual reality (VR), which replaces the physical environment with a digital one; mixed reality (MR), which allows digital and physical objects to interact; and the AI systems that enable these environments to respond intelligently to human presence and behaviour. The term is more durable than “metaverse” because it describes the underlying technological approach rather than a particular platform or business model. Spatial computing matters because it changes the fundamental relationship between human beings and digital information: from a relationship of retrieval (searching for information) to one of presence (existing within information environments). This shift has profound implications for education, work, social life, identity, and governance.

The generation that never had an offline childhood — and the myth of the digital native
Generation Alpha — broadly, those born from approximately 2010 onward — is the first generation to have grown up entirely within the smartphone era. Generation Beta, expected from approximately 2025 onward, will grow up within an era in which AI assistants are standard consumer products, augmented reality is a mainstream interface, and digital identity is as established a concept as physical identity. These generational designations are imprecise — birth years do not determine relationship to technology with the consistency that generational frameworks imply — but the underlying observation they point toward is real: cohorts of children are arriving at education systems with digital comfort levels, digital vocabulary, and digital social practices that those systems were not designed to address.
The concept of the “digital native,” coined by educator Marc Prensky in 2001, proposed that younger generations had an innate facility with digital technology that distinguished them from older “digital immigrants.” The concept has been comprehensively challenged by subsequent research, and the challenge matters. Being comfortable with technology is not the same as understanding it. A child who navigates a virtual world fluently may have no understanding of the algorithm that curates their experience within it, the data collection that monetises their presence, the ownership structures that determine what they can do and keep, or the AI systems that personalise the environment to their specific behavioural profile. Comfort and comprehension are different cognitive achievements, and conflating them produces adults who are fluent in the surface of digital systems but opaque to their structure. The OECD’s Digital Education Outlook consistently identifies this gap — between use and understanding — as one of the most significant challenges in contemporary education policy.
The classroom becomes a simulation — what immersive education actually changes
The case for immersive education is frequently made through novelty — virtual field trips to the Colosseum, simulated dissections, 3D tours of the solar system — and novelty is the weakest version of the argument. The stronger version is epistemological: immersive technology does not simply make existing educational content more entertaining. In certain domains, it changes what can be learned, because it changes what can be directly experienced.
Consider the distinction between knowing that the Great Barrier Reef is experiencing coral bleaching and being able to observe the specific visual character of that bleaching at the scale at which it occurs, in the spatial relationship between living and dead coral that a photograph cannot fully convey. Or the distinction between understanding the syntax of chemical bonding and being able to manipulate virtual molecular models that respond to the same physical constraints as their real counterparts. Or the distinction between reading about surgical procedures and practising them in a simulation environment that provides the specific tactile and visual feedback of the actual procedure without the risks of a live patient. In each case, the immersive environment does not simply represent the content differently. It allows a different quality of engagement with it — an experiential understanding that declarative knowledge alone does not provide.
The editorial question that this distinction demands is: immersive education more effective because it is more engaging, or because it changes what students can experience? The research evidence is more nuanced than the technology advocates suggest. A 2023 meta-analysis of VR-based learning interventions, cited in UNESCO’s AI and Education framework, found significant positive effects on learning outcomes in procedural and spatial tasks — surgery, anatomy, geography, engineering — but more modest effects on conceptual understanding that does not benefit from spatial representation. The technology is powerful in specific domains. It is not a universal improvement on existing pedagogy. That qualification is not a reason to resist it. It is a reason to deploy it with intelligence rather than enthusiasm.



AI becomes the tutor — personalisation, governance, and the limits of algorithmic education
Adaptive learning — educational systems that adjust content, pace, and approach to the specific learning profile of the individual student — has been a theoretical ideal of education for decades. AI makes it technically feasible at scale for the first time. A system that tracks a student’s response times, error patterns, and engagement across thousands of interactions can identify, with reasonable accuracy, whether a student is struggling with the concept, with the vocabulary, with the representation, or with attentional engagement — and adjust accordingly. The potential implications for educational equity are significant: a well-designed AI tutor could provide the kind of individualised attention that has historically been available only to students whose families could afford private tutoring.
The potential implications for educational governance are equally significant, and less frequently discussed. An AI system that continuously monitors student performance generates an extraordinary volume of sensitive data about individual children — their learning patterns, their cognitive strengths and difficulties, their attention and engagement profiles. Who owns this data? Who has access to it? How is it used beyond the immediate educational context? Does the algorithm that personalises the curriculum embed assumptions about what a student with a particular profile can achieve — assumptions that may be accurate on average but unjust in the specific case? Does the replacement of human pedagogical judgement with algorithmic recommendation reduce the role of the teacher in ways that impoverish the educational relationship beyond the measurable learning outcomes? The technology is powerful. Governance determines what that power becomes.
What is Adaptive Learning — and what are the governance questions it raises?
Adaptive learning refers to educational systems that use data about individual student performance — response accuracy, response time, engagement patterns, error types — to dynamically adjust the content, pacing, difficulty, and pedagogical approach of instruction to the specific needs of that student. AI-enabled adaptive learning systems can track thousands of data points per student per session, identifying learning gaps and strengths with a granularity that human teachers in standard classroom settings cannot match. The governance questions raised by adaptive learning concern data ownership and privacy (who controls detailed cognitive profiles of individual children), algorithmic bias (whether systems trained on historical data embed assumptions that limit expectations for certain groups of students), educational equity (whether the benefits of AI tutoring are distributed equitably or amplify existing educational inequalities), and the nature of the pedagogical relationship (whether the optimisation of measurable learning outcomes through algorithmic personalisation displaces educational goods that are less easily measured, such as critical thinking, social development, and the experience of intellectual challenge).
The new digital literacy — five capabilities the next generation actually needs
Digital literacy, as it has been defined by most educational curricula, describes the ability to use digital tools effectively: to create documents, communicate online, search for information, and navigate common platforms. This definition was adequate for the 1990s and 2000s. It is inadequate for the digital environment that is currently being built. The next generation needs a more demanding and more specific set of capabilities — not simply to use digital systems but to understand how those systems operate, who built them, what they optimise for, and what they do with the information they collect.
Five capabilities define this expanded digital literacy. The first is AI literacy: the capacity to understand what AI systems can reliably do, what they cannot reliably do, and how to evaluate their outputs critically rather than accept them as authoritative. This includes understanding how large language models generate text — through statistical pattern completion rather than genuine understanding — and why this makes them capable of producing plausible falsehoods with the same fluency as accurate information. The second is algorithmic literacy: the capacity to understand how recommendation systems shape attention, why the content a person sees is a function of algorithmic optimisation rather than editorial judgement, and what that means for the information environment in which they are operating. The third is identity literacy: the capacity to understand digital identity — how avatars, usernames, and digital representations function as both personal expression and commercial data, how authentication works, and how digital reputation is built, lost, and manipulated. The fourth is financial literacy in a digital context: understanding digital assets, online commerce, programmable economies, and the specific risks of decentralised financial systems. The fifth is security literacy: the understanding of passwords, encryption, private credentials, social engineering, phishing, and the specific vulnerabilities of digital identity that make security hygiene not a technical concern but a fundamental life skill.
The unifying principle is this: the next generation needs to understand not only how to use technology, but how technology uses them. The same generative AI that is reshaping creative industries is reshaping the information environment in which every person forms their understanding of the world — and navigating that environment without understanding its architecture is the digital equivalent of reading without understanding that texts have authors, editors, and economic interests.
Web3 without the hype — what decentralisation actually changes
Web3 has accumulated enough hype to make analytical engagement with it difficult — not because the underlying concepts are without merit but because the gap between the promise and the current reality has been consistently obscured by the promotional enthusiasm of the people building it. The underlying concepts are, nevertheless, worth examining carefully, because they address a genuine structural problem with the internet as it currently exists: the concentration of control over digital infrastructure, digital identity, and digital value in a small number of very large platform companies.
The current internet — Web2 in the vocabulary of this debate — is characterised by the extraction of value from users by platforms. Users create content, build audiences, establish digital identities, and generate the data that makes the platforms valuable. The platforms capture most of the economic value this generates. Users can be de-platformed, their audiences can be arbitrarily redistributed, and their data can be used in ways they did not consent to and may not be aware of. Blockchain technology — a distributed ledger that records transactions across a network of computers rather than on servers controlled by a single entity — proposes a different model: one in which digital ownership can be verified without the authority of a platform, in which digital assets can be held in a wallet controlled by the individual rather than an account controlled by a company, and in which the rules of digital environments can be encoded in smart contracts that execute automatically rather than implemented by platform administrators who can change them unilaterally.
The promise is genuine. The current implementation is uneven. Smart contracts can be hacked. Digital wallets can be lost. Regulatory frameworks are inconsistent. The user experience of most Web3 applications remains significantly more demanding than Web2 equivalents. Environmental concerns about proof-of-work consensus mechanisms — though substantially addressed by the shift to proof-of-stake in major networks — have not been fully resolved. The analytical position this editorial takes is the same one it takes toward immersive technology and AI: the technology is potentially significant. Governance, user experience, and regulatory frameworks will determine what that significance becomes. The application of blockchain to provenance and verification in commercial contexts demonstrates what the technology can achieve when it is deployed in service of a specific, legible problem rather than as a general proposition about the future of the internet.


The avatar as identity — what happens when self-presentation becomes programmable
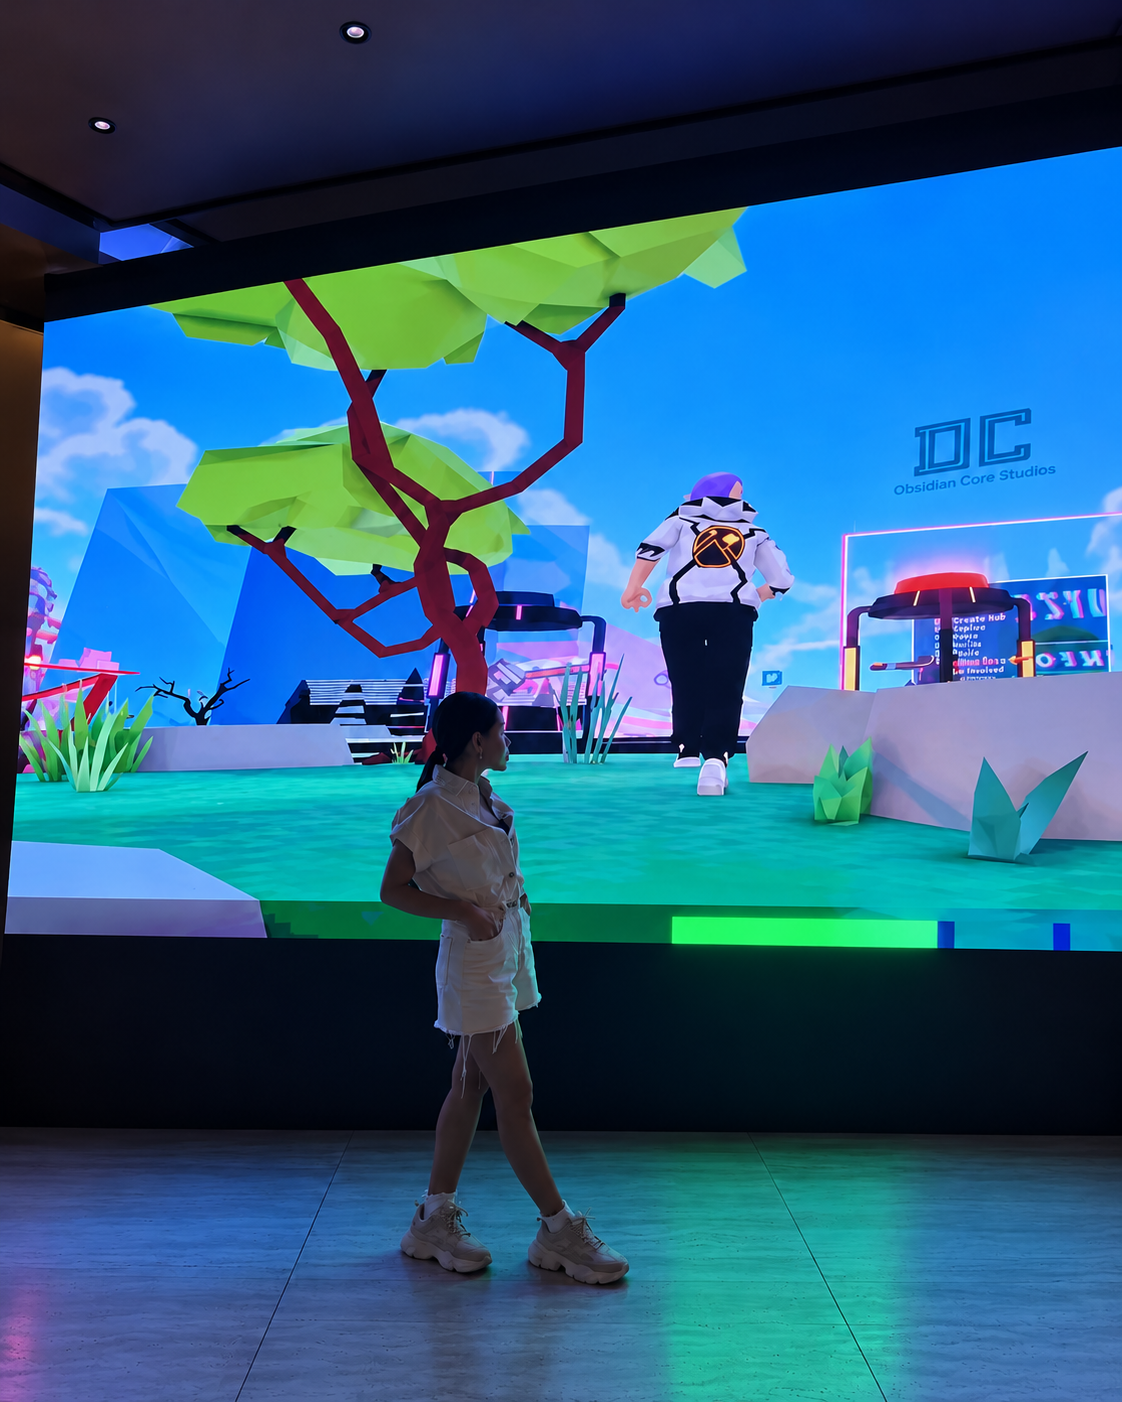
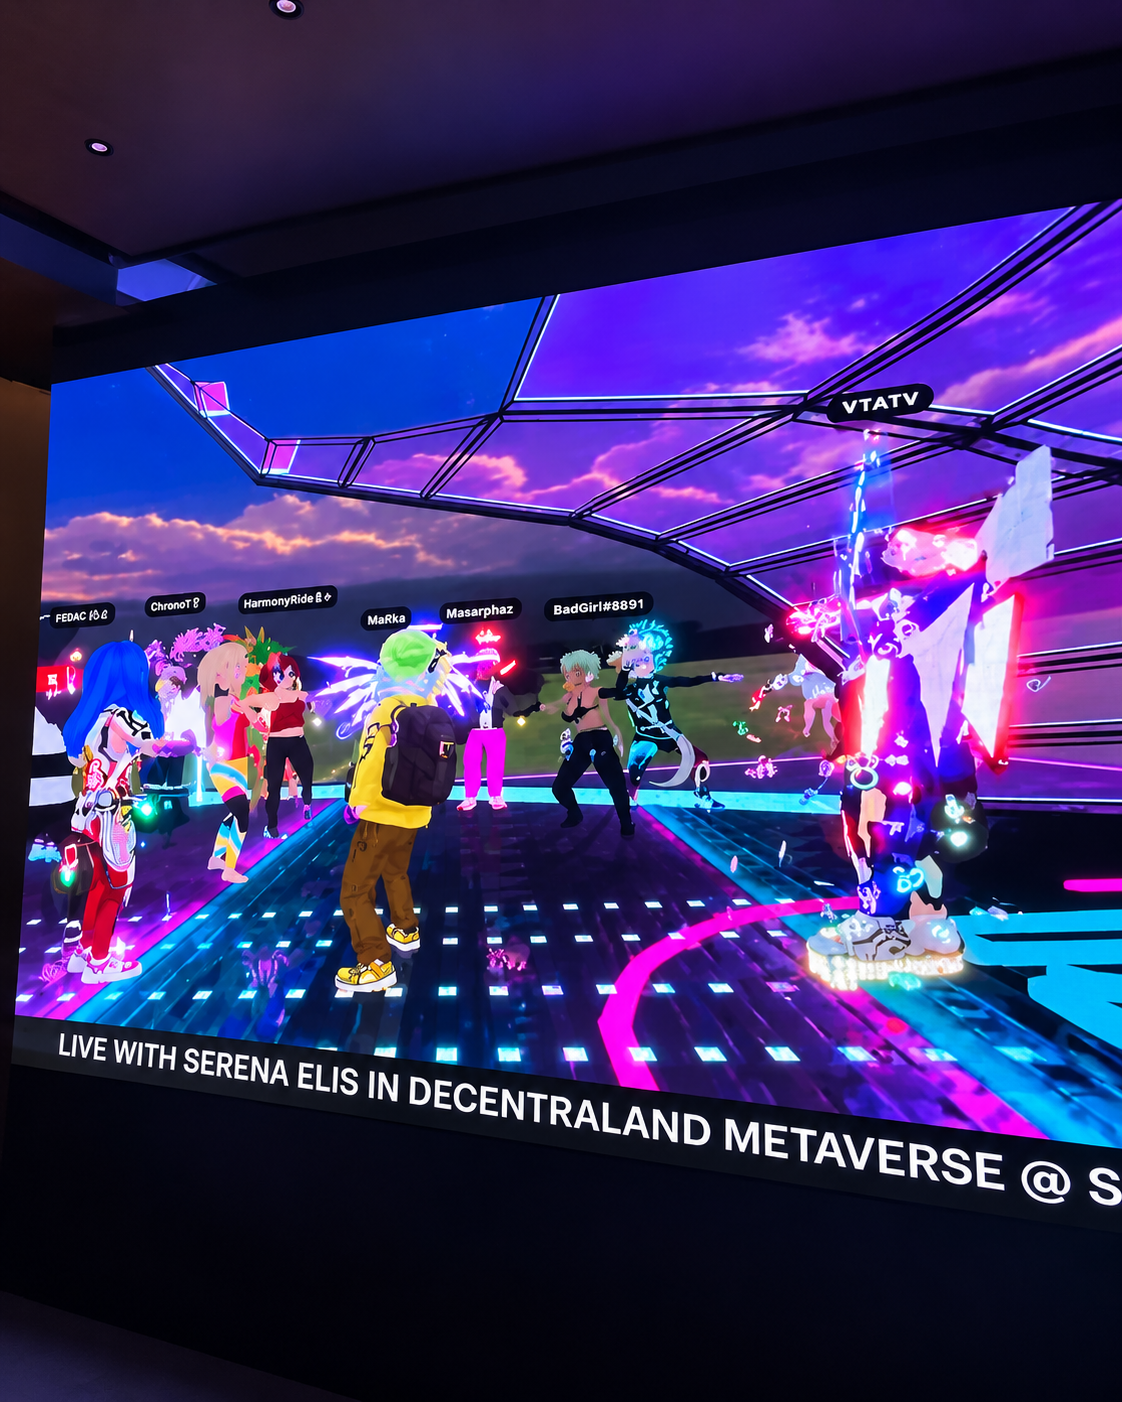
The avatar — a digital representation of the self in a virtual environment — has existed since the earliest multi-user digital environments of the 1980s. What has changed is its cultural significance and its economic weight. Platforms like Roblox, which had approximately 88 million daily active users in 2024, and Zepeto, whose user base is heavily concentrated among younger demographics in East and Southeast Asia, have demonstrated that the avatar is not simply a gaming convenience. It is a primary mode of social self-presentation, a canvas for creative expression, a fashion object, and increasingly a commercial asset whose appearance is worth real money to its owner.
The philosophical question this raises — what happens to the concept of identity when self-presentation becomes fully programmable? — is not a frivolous one. Identity in the physical world is partially constrained by physical reality: by bodies, by faces, by the accumulated history of appearance that others observe over time. Digital identity can be redesigned, multiplied, and performed differently in different contexts with a freedom that physical identity does not permit. This could be understood as a form of liberation — the ability to experiment with identity in ways that reduce the costs of self-exploration. It could also be understood as a new form of instability: an environment in which the continuity and authenticity of identity is more difficult to establish and maintain, and in which the gap between performed and experienced identity can widen in ways that have psychological consequences that research is only beginning to understand.
What is a Digital Identity — and why does it matter beyond gaming?
Digital identity refers to the collection of data, representations, and credentials that establish who a person is in digital environments. It includes usernames and accounts, avatars and digital self-representations, biometric data used for authentication, behavioural data accumulated through platform interactions, and cryptographic credentials in Web3 systems. Digital identity matters beyond gaming because it governs access to financial services, healthcare, education, and government services in increasingly digital delivery systems; because it is the primary surface through which platform companies collect the data that funds their business models; because it determines who can participate in emerging digital economies; and because its loss — through hacking, identity theft, or platform de-platforming — can have severe consequences for a person’s economic and social life. The governance of digital identity — who controls it, who can verify it, who can revoke it — is one of the most consequential unresolved questions in digital policy.

The creator economy and the new creative education
The same movement toward owning fewer, better-understood objects that is reshaping physical luxury is reshaping digital economics: creators who build with genuine craft intelligence in digital environments generate more durable value than those who simply produce volume. Roblox generated approximately $923 million in developer exchange payments to its creator community in 2023 — money paid to users, many of them young, who built the games and experiences that other users paid to access. The figure is significant not primarily as a market data point but as an educational signal: the skills required to participate in this economy — 3D design, scripting, game mechanics, community management, digital commerce — are not well represented in most standard educational curricula, despite being commercially valuable, cognitively demanding, and increasingly relevant to a broad range of professional contexts.
The broader argument is that the future internet may be characterised less by consumption of finished content and more by creation, remixing, selling, collaborating, and participating in user-generated environments. If this is accurate — and the trajectory of the most rapidly growing digital platforms supports the hypothesis — then the educational implications extend beyond adding a coding class to the standard curriculum. They concern the fundamental question of what creative and intellectual competencies are most valuable in an economy where AI can generate competent text, image, and code, and where the differentiating human contribution is increasingly in areas of design, curation, community, and judgement that require precisely the kinds of capacities that most standard educational systems least prioritise.
The infrastructure problem — digital inequality and the limits of technological optimism
The most significant experiential divides — in hospitality, in education, in digital access — are rarely about the technology itself but about who can access it at the level of quality that makes the difference. The most consequential constraint on any vision of an immersive, AI-mediated digital society is the one least discussed in technology conferences: the uneven distribution of the infrastructure required to access it. High-speed, low-latency internet connectivity — the prerequisite for any meaningful participation in immersive digital environments — remains unavailable to a significant proportion of the world’s population. The International Telecommunication Union estimated in 2023 that approximately 2.6 billion people remained unconnected to the internet. Those who are connected frequently lack access to the computing devices and processing power that immersive applications require.
This creates what might be called digital inequality 2.0. The first digital divide concerned access to the internet. The emerging digital divide concerns access to sufficiently powerful technology to participate fully in an AI-mediated, spatially immersive digital economy. A student with a low-powered smartphone and intermittent connectivity can access much of the current internet. They cannot meaningfully participate in VR-based education, AI-personalised adaptive learning, or blockchain-based digital ownership. If these technologies deliver on a fraction of their educational and economic promise, unequal access to them will translate directly into unequal outcomes — a new vector of structural disadvantage layered on existing inequalities of income, geography, and educational provision.
Who owns the digital world — the governance question that determines everything else
The question of who controls the environment — whether that environment is a designed interior space or a virtual world — is always ultimately a question about whose values are encoded in the space’s structure. The most important question about the future of immersive digital environments is not technical. It is political: who controls them? Virtual environments are not neutral spaces. They are designed objects, built with specific purposes, governed by specific rules, and monetised through specific economic models. The rules of a virtual environment — what can be done, what can be owned, who can be banned, what data is collected and how it is used — are determined by the organisations that build and operate those environments. In most current virtual platforms, those organisations are private companies accountable primarily to their shareholders.
The question of child protection in virtual environments is particularly urgent and particularly unresolved. Children interacting in virtual spaces encounter the same risks — predatory behaviour, harmful content, data exploitation, psychological manipulation through algorithmic systems — as they do on existing social media platforms, potentially amplified by the immersive quality of the environments and the stronger emotional engagement they produce. Regulatory frameworks in most jurisdictions have not yet caught up with the speed of the technology’s development. The World Economic Forum’s Future of Jobs research consistently identifies digital literacy and AI fluency among the highest-priority skill gaps in global workforce development. The EU’s AI Act and Digital Services Act represent the most comprehensive current attempt to address some of these concerns, but they were designed for the social media and AI landscape of the early 2020s, not for the spatial computing environment that is currently being built.
The governance question ultimately becomes a question about power: who gets to shape the digital environments in which the next generation will learn, socialise, work, and express identity? The answer to this question will determine more about the future of digital society than the performance specifications of any headset or the market capitalisation of any platform company. The infrastructure of trust — who can verify what, and who controls the verification — is as consequential in digital environments as it is in the physical ones they increasingly overlay.
What is the difference between Web2 and Web3 — and why does the distinction matter for digital governance?
Web2 describes the current dominant model of the internet, characterised by user-generated content hosted on centralised platforms (social media, search engines, cloud services) that are owned by private companies. Users create the value; platforms capture most of it through advertising and data monetisation. Web3 describes an emerging model built on blockchain technology, characterised by decentralisation (no single entity controls the infrastructure), user ownership of digital assets (held in individual wallets rather than platform accounts), and programmable rules (encoded in smart contracts that execute automatically). The governance distinction matters because Web2 platforms are accountable to their shareholders and subject to the regulatory jurisdiction in which they operate, creating clear lines of responsibility for harmful content or user protection failures. Web3 systems’ decentralisation makes regulatory accountability significantly more complex — there is no central operator to hold responsible when something goes wrong — while simultaneously reducing the risk of the unilateral platform decisions (de-platforming, data misuse, algorithmic manipulation) that characterise Web2’s most significant governance failures.

The digital society we are building — and the literacy that determines who can shape it
The question with which this article began — what should we be teaching the generation that will inherit the next internet? — does not have a simple curricular answer. It has a philosophical one. The most consequential educational investment that can be made for the generation growing up with AI, immersive interfaces, and programmable digital ownership is not proficiency in any specific platform or technology. Platforms will change. Technologies will be superseded. The competency that will remain valuable across all of these changes is the capacity to understand systems: how they are designed, what they optimise for, who controls them, and what they do with the people who use them.
This is a form of literacy that has no established name in educational discourse — it is something between critical thinking, systems thinking, and the specific knowledge of how digital technologies are constructed and governed. But its absence is already producing the outcome that education should most want to prevent: a generation of people who are sophisticated in the surface behaviours of digital systems and opaque to their structural logic, fluent in the vocabulary of a digital culture they do not understand and therefore cannot meaningfully participate in shaping.
The defining advantage of the coming decades will not belong to those who spend the most time in virtual worlds. It will belong to those who understand how those worlds work — and who, therefore, has the standing and the knowledge to shape them. The creative and commercial transformation that generative AI is producing across every industry — from beauty to architecture to education — is ultimately a story about the same underlying question: who has the literacy to engage with these systems at the level of their design rather than only at the level of their output? The answer to that question, for the generation currently in classrooms, is still being written. The most important thing the current generation of adults can do is make sure the writing is legible.
“The mistake would be to make this story
about the metaverse.
The metaverse may change names.
Platforms will rise and disappear.
Hardware will become smaller.
Interfaces will become invisible.
The underlying question will remain.
What happens when an entire generation
grows up believing
that the digital world
is not separate from reality?
The defining advantage
will not belong to those
who spend the most time
in virtual worlds.
It will belong to those
who understand how those worlds work —
and who gets to shape them.”

